H3-PERFORMANCE-01 · Tier B · 4.5/5
Two-regime: the schema-on-read index wins the simple lookups; the lakehouse engines win the hunting-shaped aggregations by 5–62×.
Two-regime finding: a schema-on-read index wins the simple indexed lookups; the lakehouse engines win the hunting-shaped aggregations by 5–62×, a 46.8× native / 10.1× Iceberg five-query average (Tier B, single host, 10M events, CV-gated, identical answers verified). I revised this from the earlier single-headline framing, and the revision is logged in the contradictions register. You can see how this evidence rolls up into a recommendation on the worked scorecard.
The counter-position runs along two lines. First, "ClickHouse isn't a SIEM," which is true, but the comparison is on query-engine performance against the same workload and makes no claim about the broader SIEM feature set. Second, "the workload was selected to favor columnar storage." The workload is a Zeek deployment shape, and the result generalizes most cleanly to security workloads dominated by a small number of recurring queries. A workload dominated by ad-hoc full-text search across raw events would narrow the gap.
What would change the answer: an independent benchmark on a workload with a meaningfully different shape where the schema-on-read engine closes the gap, or evidence that the ClickHouse result fails to reproduce on different hardware.
H1-COST-02 · Tier C · 3/5
Modern security data platforms cut downstream licensing costs 50–80%.
The 50–80% reduction is what a security data pipeline platform (Cribl, Tenzir, Vector, or equivalent) saves on the SIEM licensing line by filtering, downsampling, and routing at ingest, before the per-GB clock starts running. I anchor the magnitude to my own first-party MOAR cost model (a transparent $/effective-GB build you can re-run against your own volumes) and to the pipeline vendors' own published customer reductions, rather than to a survey.
The counter-position is that "downstream licensing" isn't the only cost. The pipeline platform itself carries an operational cost, and engineering time spent on routing logic is spend you'll feel. That's correct, since the 50–80% is the licensing line item and leaves out the all-in TCO. The shape I would expect in most environments is still net-positive, because the SIEM licensing line was the unforced error.
What would change the answer. A SIEM vendor moving to consumption pricing that prices the offset through, or a pipeline platform pricing model that captures the savings on its own side.
H1-PLATFORM-01 · Tier B · 4.5/5
Iceberg + Dremio + Polaris is the strongest open-stack baseline for security data.
Apache Iceberg as the table format, Dremio as the query engine, and Polaris as the catalog (the metadata layer that tells the engine what tables exist and where their data lives) is the configuration with the most production-deployment evidence behind it. Netflix runs Iceberg at multi-petabyte scale; Insider reports a 90% reduction in S3 storage cost after migrating onto this stack; Apple, AWS, Databricks, and Snowflake have all announced first-class Iceberg support since early 2025.
The counter-position: Delta Lake (the Databricks-led table format) has comparable or better tooling inside the Databricks ecosystem, and Apache Hudi has its adherents in heavy-streaming use cases. The recommendation is workload-conditional. But for the security-data workloads this practice most often sees, the Iceberg stack ends up with the strongest combination of production validation and engine portability.
What would change the answer: convergence of the table-format ecosystem (an active hypothesis on its own; see contradictions below), or evidence that a Delta-native security-data deployment outperforms the Iceberg equivalent on a comparable workload.
H-ARROW-01 · Tier B · 4/5
Apache Arrow has become the in-memory standard for cross-engine security data exchange.
Arrow is the columnar in-memory format engines use to hand data to each other without re-serialization. The 2025–2026 adoption signal is consolidating: ClickHouse Inc. shipped an official ADBC driver in February 2026 (the ClickHouse/adbc_clickhouse repo, replacing the prior community-driven driver); Trino, DuckDB, and Polars use Arrow natively; Snowflake and Databricks return Arrow on the wire; Elastic 8.16 added Arrow as a response format over REST; and in August 2026 chDB, the in-process ClickHouse engine, shipped ADBC support in v4.3.0, with the driver built into the engine library itself and listed by the ADBC Driver Foundry (Linux and macOS only). The ADBC Driver Foundry (the adbc-drivers GitHub org) is the coordination point for cross-engine driver development.
Spark moved in the same direction this year, and the Spark 4.2.0 release notes (14 July 2026) say that "Arrow-optimized Python UDFs and Arrow-based PySpark IPC are now enabled by default" (SPARK-54555), and the same release adds PyCapsule support, the Arrow C data interface, to PySpark (SPARK-54337; Tier A for what shipped). Separately, the Foundry's ADBC driver for Apache Spark came out of alpha with v0.1.0 on 20 July 2026 and reached v0.3.0 on 22 October; it is Apache-2.0, talks to Spark over Spark Connect, the Thrift protocol or Livy, and is a Foundry project rather than part of the Spark release itself (Tier B, the project's own release record). I read both as adoption signal for the trajectory claim, and because I haven't benchmarked either one yet, neither says anything here about speed.
The counter-position is that Arrow doesn't replace JDBC or ODBC for legacy tools, and not every engine reads or writes Arrow natively; some integrations still go through row-based intermediates with the per-row serialization tax. That's correct; the claim is about trajectory, not universal adoption. The operational read: "favor engines that speak Arrow on the wire," not "ban any engine that doesn't."
What would change the answer: a competing in-memory format gaining traction (no current evidence), or Arrow's per-batch overhead at extreme cardinality proving worse than alternatives on a representative security workload.
H-AI-ASYMMETRY-01 · Tier B · 4.7/5 · Settled
AI-enabled offense is maturing 2–3× faster than AI-targeted defense.
Anthropic's Claude Mythos preview demonstrated autonomous vulnerability discovery at a headline 72.4% exploit success rate on the Firefox SpiderMonkey engine, fully autonomous, no human guidance per target — a figure that collapses to roughly 4.4% once two artifact bugs are excluded from the count. The AISLE response replicated the result with eight small open-weight models in zero-shot API calls, settling the working assumption that the moat is the system, not the frontier model. Mandiant M-Trends 2026 records negative mean-time-to-exploit: exploitation is now arriving seven days before patch release. CrowdStrike clocks its fastest recorded attacker breakout at 27 seconds from initial access to lateral movement. GTG-1002, the first publicly confirmed AI-orchestrated state-sponsored campaign, was 80–90% AI-executed across roughly 30 victims.
The counter-position is that defenders also benefit from AI tooling, and the asymmetry is temporary. Both parts are true. The asymmetry is temporary; the working window is roughly 2024–2027. But "temporary" on this scale means defenders need to compress years of detection-engineering modernization into a few quarters, and the maturity gap between offensive and defensive AI tooling is wide enough that I treat this as a planning constraint, not a watch-list item.
What would change the answer: a defensive AI breakthrough that produces measurable detection-cadence gains across multiple production deployments, or evidence that the offensive results don't generalize beyond the Mythos / AISLE benchmark workload.
H-AGENT-SECURITY-01 · Tier A · 4.8/5 · Settled
AI agents with autonomous tool access need mandatory sandboxing and input validation at every trust boundary.
An agent that can reach a filesystem, a shell, a mailbox or a browser turns whatever content it reads into a possible instruction, and the record since 2025 shows that being exploited rather than theorized. Six independent sources carry the rating:
- CVE-2025-6514, a CVSS 9.6 command injection in mcp-remote's OAuth flow that let an untrusted MCP server run commands on the client machine.
- CVE-2026-25253 ("ClawBleed"), a one-click remote code execution in the OpenClaw agent through a captured gateway token.
- Kaspersky's proof-of-concept MCP supply-chain attacks, covering tool poisoning, shadowing and rug pulls.
- OWASP's AIVSS scoring work, built on the premise that conventional vulnerability scoring breaks down when an agent can change its goals mid-task.
- Microsoft's Agent Governance Toolkit, which ships those boundary controls as code.
- GTG-1002, the AI-orchestrated espionage campaign Anthropic detected in mid-September 2025 and disclosed that November.
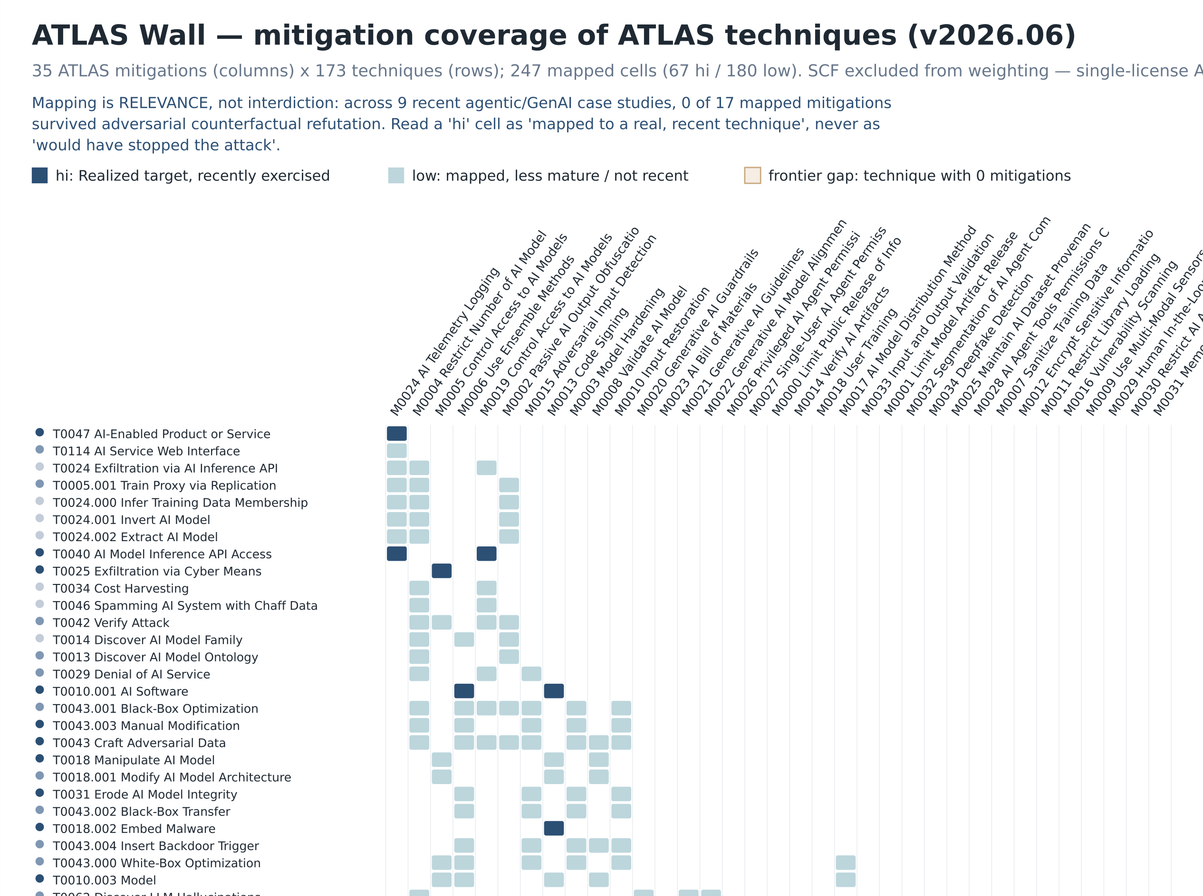
I keep a settled claim on this list because it's the securing-AI position the rest of the site leans on. The lethal trifecta works it as a design rule, where you remove one leg (private data, untrusted content, a way out) rather than trust a filter to catch the injection, and the ATLAS Wall scores the controls that map to it.
The counter-position is that guardrail models and prompt-injection classifiers keep improving, so a well-tuned filter could eventually carry the weight a sandbox carries today. I don't think the evidence supports that yet, because OWASP's 2025 entry on prompt injection says it is unclear whether fool-proof prevention methods exist, and the practitioners I track, Simon Willison among them with his line that 95% is a failing grade, keep converging on hard boundaries over probabilistic ones.
What would change the answer: a probabilistic control, a classifier or an LLM judge, holding up under adaptive attack in a published, independently reproduced evaluation, at a miss rate low enough that a security team would accept it in place of a sandbox.
H-COST-09 · Tier A/B · 4/5
Tiered storage cuts up to about 90% of long-tail security data cost.
Splitting security data across hot, warm, and cold storage tiers (hot on local high-performance storage, warm on cheaper attached storage, cold on S3 Standard, archival on S3 Glacier or equivalent) reduces the long-tail cost of retention by up to about 90% in the one production case I can source (Insider), which documents a 90% S3 cost reduction after tiering; current S3 list prices put the colder classes between 46% and 96% below S3 Standard per GB-month, before retrieval fees and minimum-duration charges; Stanislav Kozlovski's KIP-405 analysis puts the Kafka-side saving at about 6×; and Kafka 3.9+ supports tiered storage natively (KIP-405, early access since 3.6), which has materially changed the operational story for streaming security telemetry.
The counter-position is the freshness trade-off. Warm and cold tiers have higher first-byte latency than hot tiers; queries that span tier boundaries pay a complexity tax. For interactive threat hunting on recent data, the tiering boundary needs to land further back than for compliance retention. Most engagements end up with a tier boundary at 7–30 days; some land at 72 hours where the analyst hunting window is short.
What would change the answer: object-storage pricing collapsing to the point where tiering's operational complexity isn't worth the savings, or query-engine improvements that make cross-tier queries effectively free.
H3-INTEGRATION-03 · Tier B · 4/5
OCSF earns its keep as a normalization hygiene baseline, not as the schema everyone finally agrees on.
OCSF (the Open Cybersecurity Schema Framework) is the shared event-shape standard adopted by 180+ organizations, including AWS Security Lake, Cisco, Sumo Logic, IBM, Cloudflare, and many of the EDR vendors, and ITU-T Study Group 17 is standardizing it as Recommendation X.icd-schemas, with member states backing it for standardization, a process still working through Study Group 17 as of this writing. Where I think OCSF actually pays off is narrower than the adoption numbers suggest: as a fixed reference shape that a pipeline can be graded against, it catches the silent field-mapping failures that schema-on-read hides until a detection quietly stops firing, and in one recursive-mapping pipeline I watched that conformance reference take an LLM's mapping accuracy from roughly 80% to 95% precisely because the model had something to be checked against. That machine-grounding value is real, and it's the part I'd build on. I'm more bearish on OCSF as a human lingua franca, the version where every vendor converges its analyst-facing semantics onto one shared model, because when I mapped six source schemas (CIM, UDM, ASIM, ECS, OpenTelemetry, Zeek) into OCSF 1.8.0 the same five normalization gaps recurred across all of them, and those gaps are OCSF's own (required severity_id with no source field to fill it, missing disposition on several activity classes, one-to-many change routing), so the mapping stays expert labor rather than collapsing into a standard a SOC analyst can wield by hand. Sigma plays the matching role one layer up, keeping detection logic portable across engines so a schema change and an engine change don't both force a detection rewrite.
The honest counter-position isn't scale. OCSF already runs in named production at real volume, and the largest public figure I've found is Atlassian's, about 44 billion security events a day normalized to OCSF according to a Databricks blog co-written with Atlassian engineers in October 2026 (Tier C, vendor co-authored, with no bytes-per-day figure and no method), though the petabyte-a-day claims I keep hearing still haven't been independently verified. It's that an open schema doesn't by itself defeat lock-in: the governance and authorization layers above the schema are where the remaining vendor capture lives, and OCSF says nothing about those. An open event shape sitting on a closed catalog is still a closed system.
What would change the answer: a competing schema gaining vendor-consortium momentum, or OCSF normalization proving materially lossy on a major source class at scale, forcing per-vendor escape hatches that re-introduce the lock-in the schema was meant to remove.
H-SIGMA-01 · Tier B · 3/5 · Caveat
Sigma extends portability to the detection layer. Strong for atomic rules, bounded for correlation.
Open data formats and an open schema move security telemetry across tools without translation tax; what they don't move is the detection content itself, which is still authored in whatever query language the engine happens to speak. Sigma fills that gap: a YAML rule that compiles to ClickHouse SQL, Splunk SPL, Sentinel KQL, or Elastic ESQL via pySigma. SigmaHQ ships thousands of community rules; vendor adoption is broadening (Anvilogic, Panther, hand-rolled patterns in production SOCs).
Caveat: portability is strong for atomic detections (single-event matching), weaker for stateful correlation (sliding windows, sequence matching, deduplication). Vendor-native languages tend to be more expressive than Sigma's intermediate representation, and lossy conversions exist. Sigma 2.0 correlation extensions are not yet proven at production scale. So the framing I use is that detection portability is real but bounded: author the atomic layer in Sigma, and accept that the correlation layer may stay engine-specific.
What would change the answer: a competing detection standard gains vendor-consortium momentum, or Sigma 2.0 correlation proves unworkable on production-scale stateful detections.
H-IMPL-01 · Tier D · 2/5 · Reasoned
Streaming architectures cost meaningfully more to operate than batch equivalents.
Real-time streaming architectures cost more to operate than equivalent batch architectures, and the premium shows up in three places: specialized staffing (streaming competence is scarcer and more expensive to hire and retain than batch ETL skills), infrastructure redundancy (always-on Kafka and Flink clusters rather than scheduled spot batch), and incident-management surface (an always-on pipeline has more that can fail unattended than a batch job that simply reruns). The exact multiplier depends on the environment; the direction is consistent.
Caveat: this is a reasoned operational claim from the mechanism above, not a measured multiplier, and I've dropped the specific premiums some write-ups attach here (a DORA staffing figure, IDC / Enterprise Data Quarterly incident rates) because they don't survive a primary-source check, so until my own lab run below the direction stood on the mechanism alone. Security workloads have particular shapes (high-cardinality entity resolution, bursty incident-driven query loads, regulatory retention) that may shift the gap in either direction. My own lab has since measured the direction on one detection, which is what moved this from 1/5 to 2/5: on a single host, Kafka plus Flink ran 4× the moving parts of a batch job and needed more recovery steps after faults (4 against 3), and on a real-time clock it bought about 3 seconds of median alert freshness for that (SDW Lab results, Tier B). That measures direction only, because dollars, headcount and on-call burden stay unmeasured, so a security-specific TCO comparison (streaming SIEM vs batch lake on the same workload) is still on the research backlog.
The counter-position is that detection latency requirements force streaming for some workloads regardless of cost. That's true, and what follows from it is to stream what needs streaming, batch the rest, and budget for the operational cost differential, which is real.
What would change the answer: a published security-specific TCO comparison — either confirming the general data-engineering finding or showing the security workload shape narrows the gap.
H-NDR-FEDERATION-01 · Tier B · 4/5
Federated search architecture determines NDR platform stickiness.
The network-detection-and-response (NDR) market is consolidating around platforms that can federate search across multiple data sources without forcing centralization first. The argument is capability-led, not cost-led: federated query enables cross-site joins, data sovereignty (EU data stays in EU jurisdictions), and much less wide-area-network traffic, because the query goes to where the data lives rather than shipping the data home. Centralized SIEMs cannot deliver any of these at any price.
More than 50 federated security implementations are publicly documented. ExtraHop is an early Security Lake federation partner; AWS Security Lake plus Athena is becoming the lowest-effort bridge for shops already on AWS; CrowdStrike has not yet shipped a standardized federation API, which is a competitive opening for the platforms that have.
What would change the answer: a centralized SIEM vendor solving the cross-site / data-sovereignty problem without forcing centralization (no current evidence this is happening), or evidence that federation performance overhead at scale is worse than the early benchmarks suggest.
H-AGENT-SCALE-DATA-LAYER-01 · Tier C · 3/5 · Deep dive
Security-data infrastructure for agent-scale workloads
As security work shifts toward agents, the binding constraint is the data layer rather than the model or the policy layer on top, so the vendors that matter are the ones rebuilding the security-data infrastructure for agent-scale access while the rest bolt AI onto BI-era stacks. This hypothesis is carried in full on its own page, with the convergent evidence, the validation gaps, and what would change the answer.
Read the full deep dive →